
The core defense against non-human identity risk is straightforward: inventory every service account, assign a named human owner, remove static secrets, apply least privilege, automate credential rotation, and monitor behavior for deviations. Organizations that skip any one of these six controls tend to accumulate the orphaned, over-privileged accounts that show up in nearly every breach investigation involving service credentials. The guidance below draws on SANS Institute research, CISA's hybrid identity recommendations, and NIST's automated account management standards.
TL;DR:
- Regularly inventory all service account types across on-premises and cloud environments, focusing on owners, purpose, privilege level, and usage history.
- Assign a human owner to every service account at creation, enforce automated provisioning and deprovisioning, and set review and expiration dates to prevent orphaned accounts.
- Replace static secrets with vault-based retrieval systems and migrate workloads to credential-less authentication methods like workload identity instead of long-lived keys.
- Continuously monitor baseline behavior patterns of service accounts to detect anomalies, such as new endpoints, unexpected data volume, or multi-region activity, for high-confidence breach detection.
- Implement phased remediation starting with discovery, then disabling high-risk accounts, assigning ownership, right-sizing permissions, migrating to workload identity, and automating reconciliation and monitoring.
Table of Contents
- What Makes Service Accounts Different From Human Accounts
- Where Service Account Risk Actually Hides
- How To Discover and Inventory Every Non-Human Identity
- Assigning Ownership and Enforcing the Account Lifecycle
- Right-Sizing Permissions Without Breaking Production
- Eliminating Static Secrets and Managing Credentials Properly
- Moving Away From Static Credentials Entirely
- Building Behavioral Baselines That Actually Catch Compromise
- Automating Reconciliation and Decommissioning Safely
- A Phased Remediation Roadmap for SMB Teams
- How Symmnet Supports Service Account Governance for SMBs
- The Trade-Offs Nobody Puts in the Checklist
- Get Help Implementing Service Account Controls
- Sources
What Makes Service Accounts Different From Human Accounts
A service account is a non-human identity that lets software authenticate and act, rather than a person logging in. The category covers several distinct mechanisms: local operating system service accounts, service principals in cloud platforms like Azure and Google Cloud, API keys issued to applications, managed identities that platforms assign automatically, and OAuth tokens that grant temporary scoped access. Each behaves differently, but all share one trait that separates them from human logins: they run continuously, without a person present to respond to a prompt.
That absence changes everything about how you secure them. A human employee can approve a push notification or type a one-time code. A batch job running at 2 a.m. cannot. Traditional multi-factor authentication was built around the assumption that a person is on the other end of the login, and service accounts break that assumption entirely.
Three operational differences matter most for security teams building policy around non-human identities:
- Continuous operation. Service accounts don't log off. A compromised credential can be used around the clock without triggering the "unusual login time" alerts that catch human account abuse.
- No interactive enrollment. You can't ask an API key to complete a FIDO2 registration. Phishing-resistant authentication has to be engineered into the platform, not requested from the user.
- Predictable call patterns. A backup script hits the same endpoints, at the same volume, on the same schedule, day after day.
That third trait is actually an advantage. SANS Institute research on applying zero trust to non-human identities notes that because service accounts behave so predictably, deviations from their baseline pattern are high-confidence signals of compromise. A human's behavior varies too much to baseline reliably. A service account's doesn't, which is exactly why behavioral monitoring works so well against this identity class when applied correctly.
Where Service Account Risk Actually Hides
Every environment has a mix of service account types, and each type tends to accumulate risk in a different place. Mapping the type to its typical leakage point is the fastest way to know where to look first.
On-premises Windows environments still run standard OS service accounts with passwords that rarely get changed, alongside Group Managed Service Accounts (gMSA) and standalone Managed Service Accounts (sMSA), which Microsoft designed specifically to auto-rotate credentials without human intervention. Cloud platforms use service principals (Azure), service accounts (Google Cloud), and IAM roles (AWS) to grant applications scoped permissions. Layered on top of all of that: API keys issued to third-party integrations, and short-lived tokens generated for CI/CD pipelines and containerized workloads.
The leakage points repeat across nearly every environment we've seen:
- Hardcoded credentials committed to source repositories, often years before anyone notices
- Secrets printed into build logs during CI/CD pipeline runs
- API keys baked into container images instead of injected at runtime
- Configuration files and environment variables that persist long after a deployment ends
- SaaS integrations authorized once and never revisited
Pro Tip: Before deploying gMSA, confirm your Active Directory environment supports the Key Distribution Service (KDS) root key setup. A surprising number of SMB teams start a gMSA migration, hit that prerequisite gap, and quietly fall back to a standalone user account with a password that never expires. Document the prerequisite checklist before you start, not after the rollback.
How To Discover and Inventory Every Non-Human Identity
You cannot govern what you haven't found. Discovery has to happen across every layer of your stack, because service accounts get created in whatever system was fastest at the time, not in a place anyone tracks by default.
Pull from these sources systematically:
- Active Directory and identity providers — query for accounts with non-expiring passwords, accounts never used interactively, and accounts with "svc" or "app" naming patterns.
- Cloud IAM consoles (AWS IAM, Azure Entra ID, Google Cloud IAM) — export service principal and role lists with last-used timestamps.
- Secrets managers and vaults — inventory every stored credential and cross-reference against which application actually calls it.
- CI/CD platforms and source repositories — run secret-scanning tools against commit history, not just the current branch.
- Container registries — scan images for embedded credentials before they reach production.
- SaaS admin consoles — list every connected app and API integration, since these are the accounts security teams forget fastest.
An inventory record that's actually useful for governance needs more than a name. Track the owner, business purpose, credential type, privilege tier, last-used date, and an expiration or review date for every entry. Without that metadata, your inventory is a list, not a control.
Pro Tip: Automate the reconciliation job that compares your inventory against live systems weekly, not quarterly. A service account created outside the approved workflow shows up within days if the job runs weekly; it can sit undetected for a year if you only check once a quarter.
Assigning Ownership and Enforcing the Account Lifecycle
Every service account needs a named human owner from the moment it's created, not assigned retroactively after an audit flags it. That owner is accountable for the business justification, the review cadence, and the decision to retire the account when it's no longer needed. An account with no owner is an account nobody notices when it should be disabled.
Apply the same joiner/mover/leaver discipline you use for human employees to non-human identities. When a project ends, the service account tied to it should be disabled automatically, not left running because nobody remembered it existed.
Practical governance controls that hold up under audit:
- Require business justification and an expiration or review date at account creation, not as an afterthought
- Automate provisioning and deprovisioning through your identity provider's SCIM connector wherever the target system supports it
- Use ITSM workflows to trigger reviews on a fixed schedule for accounts too old for automated connectors
- Run reconciliation jobs against legacy systems that lack SCIM support, since those systems are exactly where orphaned accounts hide longest
- Define a documented break-glass procedure for emergency access, with automatic expiration and mandatory post-use review
NIST's automated system account management guidance under AC-2(1) treats this kind of automated lifecycle enforcement as a baseline control, not an enhancement. Auditors increasingly expect to see reconciliation logs and provisioning records as evidence, not just a policy document describing what should happen.
Right-Sizing Permissions Without Breaking Production
Most service accounts accumulate permissions faster than anyone strips them away. A developer grants broad access to unblock a deployment, the deadline passes, and nobody circles back to tighten it. Reducing that privilege safely requires a process, not a one-time cleanup sprint.
- Baseline current usage. Pull 30 to 90 days of access logs to see which permissions an account actually exercises versus which ones it merely holds.
- Analyze the gap. Compare granted permissions against used permissions. The difference is your reduction target.
- Propose a right-sized role. Build from role templates or entitlement bundles where possible, since a repeatable template is easier to audit than a one-off permission set.
- Run in observation mode. Apply the new permission set in a monitoring-only configuration first, logging what would have been denied without actually blocking it.
- Enforce and monitor. Once observation shows zero unexpected denials over a full cycle, switch enforcement on and keep watching for a defined period afterward.
The least privilege implementation guide covers role template design in more depth if you're building this from scratch.
Coordinate with the account owner before every enforcement step, and keep a rollback plan ready. If a legitimate but rarely used function gets blocked, you want to restore access in minutes, not file a change ticket and wait a day while a production process stalls.
Eliminating Static Secrets and Managing Credentials Properly
The single most common failure in service account security is a secret sitting somewhere it shouldn't: in a code repository, baked into a container image, or dropped into an environment variable that outlives the process that needed it. None of that is acceptable once you have an alternative, and today you almost always do.
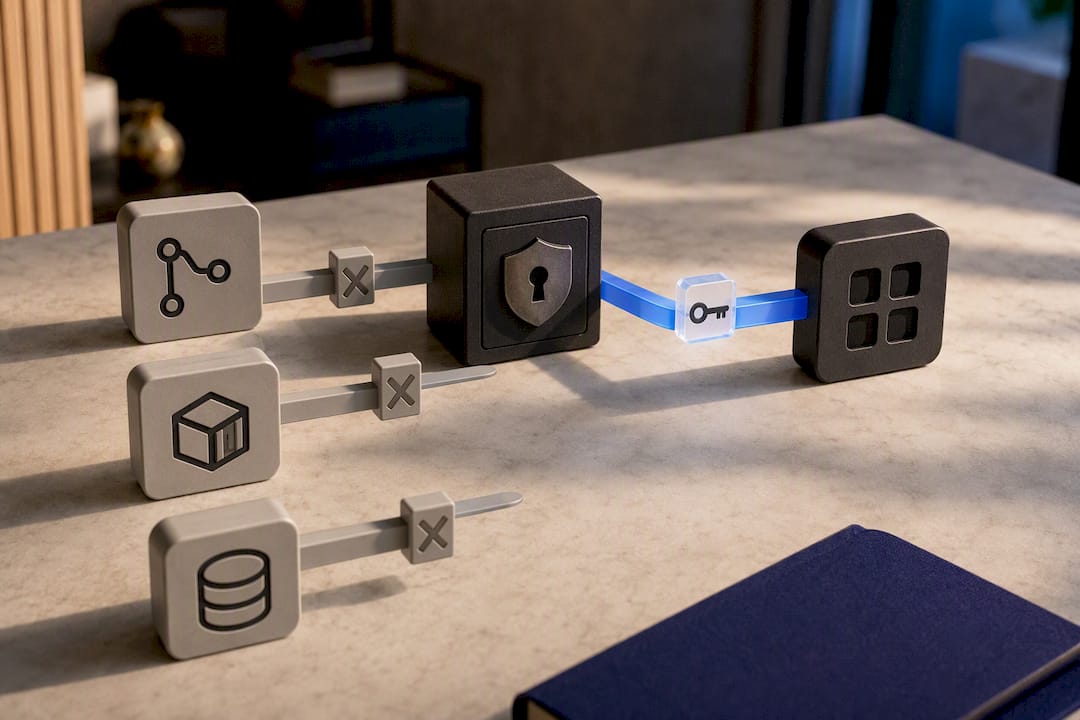
The rule set is simple to state and hard to enforce without tooling: never store secrets in source code or container images, centralize every credential in a secrets manager or vault, retrieve secrets at runtime rather than persisting them to disk or environment variables, and treat any secret found in a repository as compromised the moment it is discovered.
Categories of vault platforms that handle this well include self-hosted options like HashiCorp Vault and cloud-native services like AWS Secrets Manager and Azure Key Vault. Which one fits depends on your existing cloud footprint more than any feature difference between them.
Rotation frequency should match sensitivity rather than following one blanket schedule. Guidance from StartWithIdentity's service account security research suggests rotating high-privilege credentials roughly every 30 days and standard-tier credentials every 90 days, automated rather than manual in both cases.
Use a staged atomic swap when rotating: provision the new credential, update every dependent system in parallel, verify the new credential works, and only then revoke the old one. Rotating first and updating dependencies second is how rotation projects turn into outage tickets. CISA's own countermeasures guidance on resetting service account passwords flags this exact risk, noting that password resets can disrupt dependent services if the impact isn't mapped and documented beforehand.
Pro Tip: Run a secret-scanning tool against your full repository history, not just the current branch. A credential removed from today's code but still sitting in a commit from eighteen months ago is just as exploitable as one sitting in production.
- Scan repositories and container images before merge and before build, not after deployment
- Rotate any secret a scanner flags immediately, then investigate how it got there
- Purge exposed secrets from version history, since deleting the current file leaves the commit log intact
Moving Away From Static Credentials Entirely
The strongest long-term fix for credential risk isn't better rotation. It's removing the static credential altogether. Each major cloud platform now offers a pattern that lets workloads authenticate without a stored secret ever existing.
Azure Managed Identities let a resource authenticate to other Azure services without any credential a developer has to manage. AWS IAM Roles for Service Accounts (IRSA) does the equivalent for workloads running in Kubernetes on AWS, issuing short-lived tokens tied to a Kubernetes service account rather than a long-lived access key. Google Cloud's Workload Identity Federation extends the same idea further, letting external workloads authenticate using federated identity instead of a downloaded service account key file.
The operational trade-off is upfront setup complexity in exchange for eliminating an entire class of leak risk. There's nothing to rotate and nothing to accidentally commit to a repository, because there's no static secret in the first place.
Prioritize the migration in this order:
- New workloads first. Building on workload identity from day one costs far less than retrofitting it later.
- High-privilege accounts second. The accounts with the most damage potential should shed their static credentials before lower-risk ones do.
- Legacy systems last, if at all. Some on-premises legacy applications genuinely can't support federated identity, and forcing the migration anyway isn't worth the engineering cost.
Keep a rollback plan for each migration wave. CISA's hybrid identity solutions guidance recommends favoring phishing-resistant authentication methods, such as certificate-based and PKI-backed approaches, over password or shared-secret models wherever the platform supports the switch.
Building Behavioral Baselines That Actually Catch Compromise
Login-based monitoring, the model built for human accounts, largely fails against non-human identities. A stolen service account credential logs in successfully every time; there's no failed-password pattern to catch. What catches compromise is watching what the account does after it authenticates, not whether the authentication itself succeeded.
Behavioral baselining means tracking the API call sequences, destination endpoints, data volume, and timing pattern a given service account exhibits under normal operation. SANS research on applying zero trust principles to non-human identities found that because these patterns are so consistent for legitimate service accounts, deviations from baseline carry unusually high confidence as compromise indicators, far higher than the equivalent deviation would carry for a human user.
Specific detection rules worth building into your monitoring pipeline, roughly in priority order:
- New destination endpoints the account has never called before, especially external or internet-facing ones
- Unexpected data volume, particularly a sudden spike in records pulled or exported
- Simultaneous multi-region activity from an account that normally operates from one location
- Any interactive login attempt on an account provisioned exclusively for machine-to-machine use, which should never happen and should alert immediately
Centralize the logs feeding these rules. AWS CloudTrail, Microsoft Entra ID sign-in logs, and application-level audit logs all need to land in one SIEM or analytics pipeline, because correlating a single account's behavior across three separate log sources in real time isn't realistic during an active incident.
Build a triage playbook that escalates to the account owner automatically and applies temporary throttling to suspicious activity while the investigation runs, rather than waiting for a full manual review before taking any action. That approach keeps the blast radius small without requiring a security analyst to be watching the dashboard at the exact moment the deviation occurs.
Automating Reconciliation and Decommissioning Safely
An inventory is only accurate on the day you build it unless something keeps it current. That something has to be automation, because manual reconciliation degrades within a quarter no matter how disciplined the team.
- Run automated reconciliation jobs. Use SCIM connectors wherever your identity provider and target system both support them, and build lightweight reconciler scripts for the legacy systems that don't.
- Auto-generate remediation tickets. When reconciliation finds a discrepancy, drift, or an orphaned account, the finding should open a ticket with an SLA attached automatically, not sit in a report nobody reads.
- Decommission in stages, never all at once. Disable the account first, monitor for roughly 30 days to confirm nothing breaks, then delete the account and purge its credentials from every vault and configuration store.
- Preserve the audit trail. Keep the disable date, the monitoring window's findings, and the final deletion record together as one evidence artifact.
- Run periodic control health checks. Confirm the reconciliation job itself is still running, still connecting to every target system, and still generating tickets, since a silently broken reconciliation job is worse than no reconciliation at all.
NIST's account management standard treats this kind of automated reconciliation and evidence capture as the mechanism that makes AC-2(1) defensible during an audit. Save every reconciliation output and remediation ticket. Auditors ask for proof the control operated, not just a policy stating that it should.
A Phased Remediation Roadmap for SMB Teams
Trying to fix everything simultaneously is how service account remediation projects stall. A phased approach, moving from the highest-risk quick wins toward full automation, gets real risk reduction on the board within weeks rather than waiting for a perfect long-term architecture.
- Phase 1, Discover (weeks 1 to 2): Build the full inventory across AD, cloud IAM, secrets managers, and CI/CD systems.
- Phase 2, Protect quick wins (weeks 2 to 4): Disable orphaned high-privilege accounts immediately and move any exposed credentials into a vault.
- Phase 3, Assign ownership (weeks 3 to 5): Attach a named owner and review date to every account in the inventory.
- Phase 4, Right-size privilege (weeks 5 to 10): Run the baseline to observe to enforce cycle on your highest-risk accounts first.
- Phase 5, Migrate to workload identity (weeks 8 to 16): Shift new workloads and high-privilege accounts to credential-less authentication patterns.
- Phase 6, Automate and monitor (ongoing): Stand up reconciliation jobs, behavioral baselining, and the triage playbook, then keep them running.
| Phase | Primary goal | Typical timeframe |
|---|---|---|
| Discover | Complete inventory with owners identified | 1 to 2 weeks |
| Protect quick wins | Orphaned accounts disabled, secrets vaulted | 2 to 4 weeks |
| Assign ownership | Every account has a named owner and review date | 3 to 5 weeks |
| Right-size privilege | High-risk accounts reduced to least privilege | 5 to 10 weeks |
| Migrate to workload identity | Static credentials replaced on priority accounts | 8 to 16 weeks |
| Automate and monitor | Reconciliation and baselining running continuously | Ongoing |
Report progress with metrics leadership and auditors both understand: the percentage of accounts with a named owner, the count of accounts still holding static long-lived credentials, and the number of accounts successfully migrated to workload identity federation. Those three numbers, tracked monthly, tell you exactly how much risk you've actually removed.
How Symmnet Supports Service Account Governance for SMBs
Building and maintaining every control above takes dedicated time most SMB IT teams don't have to spare, especially on top of daily helpdesk demands and existing compliance obligations. Symmnet's managed IT and cybersecurity services were built around exactly that gap: 24/7 system monitoring, endpoint security, and firewall management paired with the compliance documentation manufacturers, aerospace suppliers, and professional services firms are already expected to maintain.
For businesses operating under FDA, ITAR, or AS9100 requirements, service account governance isn't optional paperwork. It's audit evidence regulators and customers ask to see. Compliance assistance and network segmentation can help small businesses document ownership, credential handling, and access reviews in a form that holds up when an auditor or a customer's security team asks for proof.
If your organization hasn't inventoried its service accounts, or isn't confident every credential has an owner and a rotation schedule, a free assessment is the practical starting point. It identifies where accounts have accumulated unmanaged privilege before that gap turns into an incident report.
The Trade-Offs Nobody Puts in the Checklist
Every service account framework reads clean on paper. In practice, SMB teams run into the same wall every time: legacy systems that predate any of this thinking, and a staff too small to build custom tooling for every gap. That's the honest starting point for prioritization, not a reason to skip the work.
My take, after walking through this framework end to end: the phased roadmap matters more than any single control on the list. Teams that try to fix everything at once burn their first month building an inventory spreadsheet nobody maintains past week six. Teams that disable the three orphaned admin accounts they find in week one, then move to ownership assignment, get real risk reduction on the board immediately.
Decide early what stays in-house and what gets outsourced. Inventory and ownership assignment are judgment calls only your team can make correctly. Round-the-clock behavioral monitoring and reconciliation automation are exactly the kind of ongoing operational load a managed IT partner is built to carry. There's no universal ratio. There's just an honest inventory of what your team can sustain past the first quarter.
— Michael
Get Help Implementing Service Account Controls
A phased remediation plan only works if someone owns it week over week, and that's exactly where most SMB teams stall out after the initial inventory sprint. Ongoing services providing monitoring, endpoint security, and compliance documentation can ensure that reconciliation jobs and behavioral alerts continue after the first audit.
If your team is manufacturing, aerospace, or another regulated sector already managing audit evidence for other controls, folding service account governance into that same compliance workflow is far more efficient than running it as a separate initiative. Symmnet's managed IT services cover exactly that integration, from vault deployment to ongoing monitoring. Start with a free assessment to see which of your service accounts carry the highest unmanaged risk right now.
Sources
- The Agent Identity Problem: Applying Zero Trust to AI Agents | SANS Institute
- NIST SP 800-53: AC-2(1) Automated System Account Management (summarized)